Morning market digest
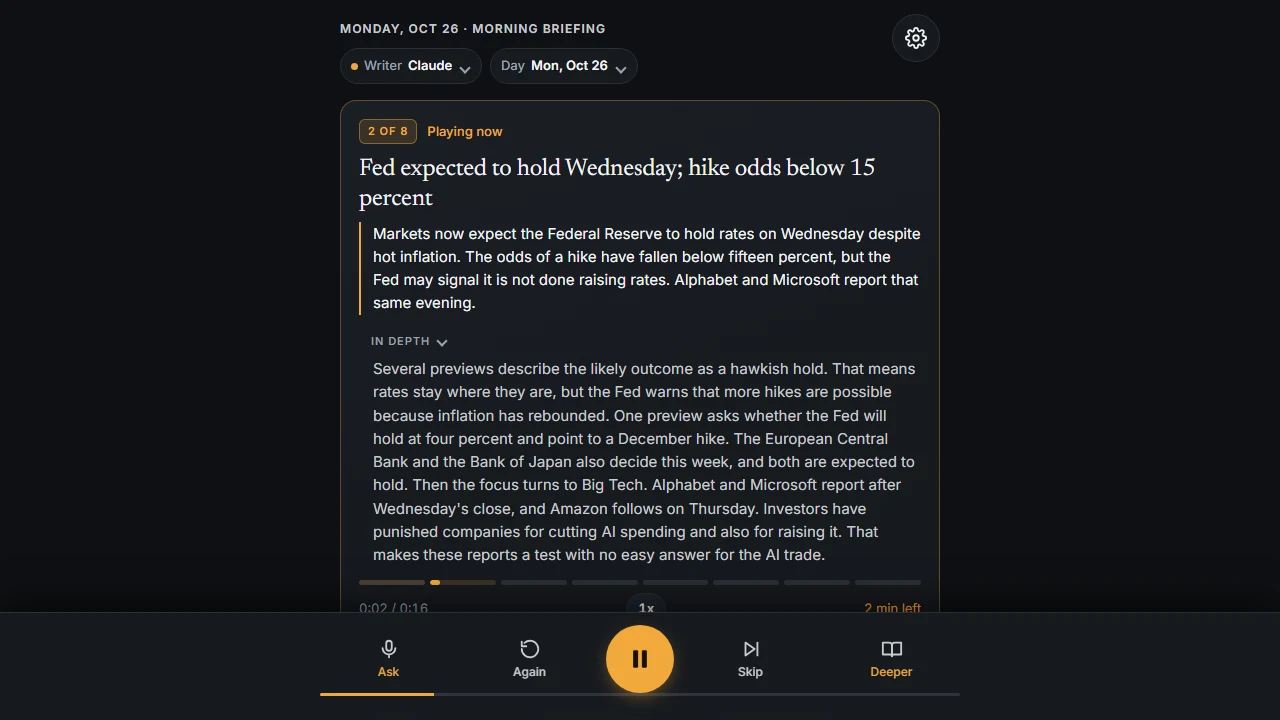
A spoken market briefing that writes itself every morning. Claude writes it, a local model on my own GPU steps in if Claude can't, and I can ask follow-up questions out loud.
01 / problem
I invest for the long term and buy big dips, so a ticker feed is noise. I wanted a few minutes each morning covering only what matters to that: a short watch list, market-stress signals and the news behind them, read to me while I get ready.
02 / approach
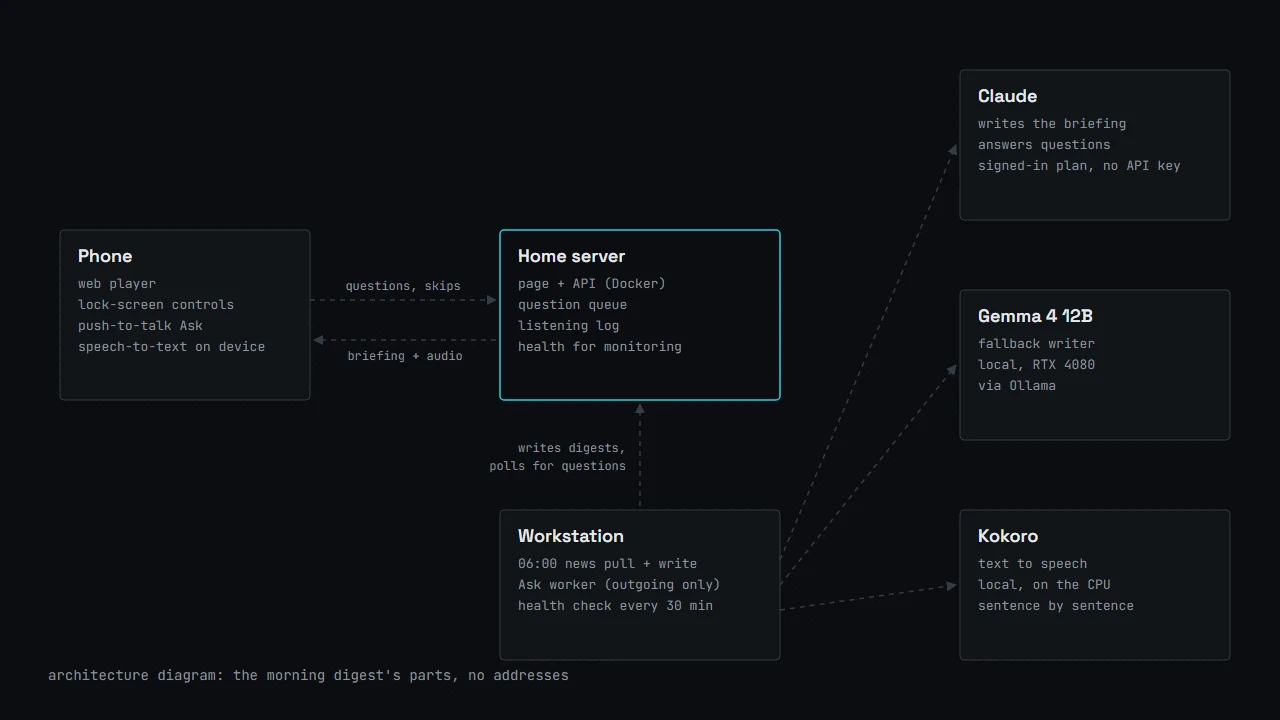
Each morning the workstation pulls news from free feeds and searches. Claude writes the briefing through my signed-in Claude plan, with no API key. Gemma 4 12B on an RTX 4080 at home writes it if Claude fails, and Kokoro reads it in a local voice. I picked the writer by running Claude, Gemma and gpt-oss on the same news pull.
03 / result
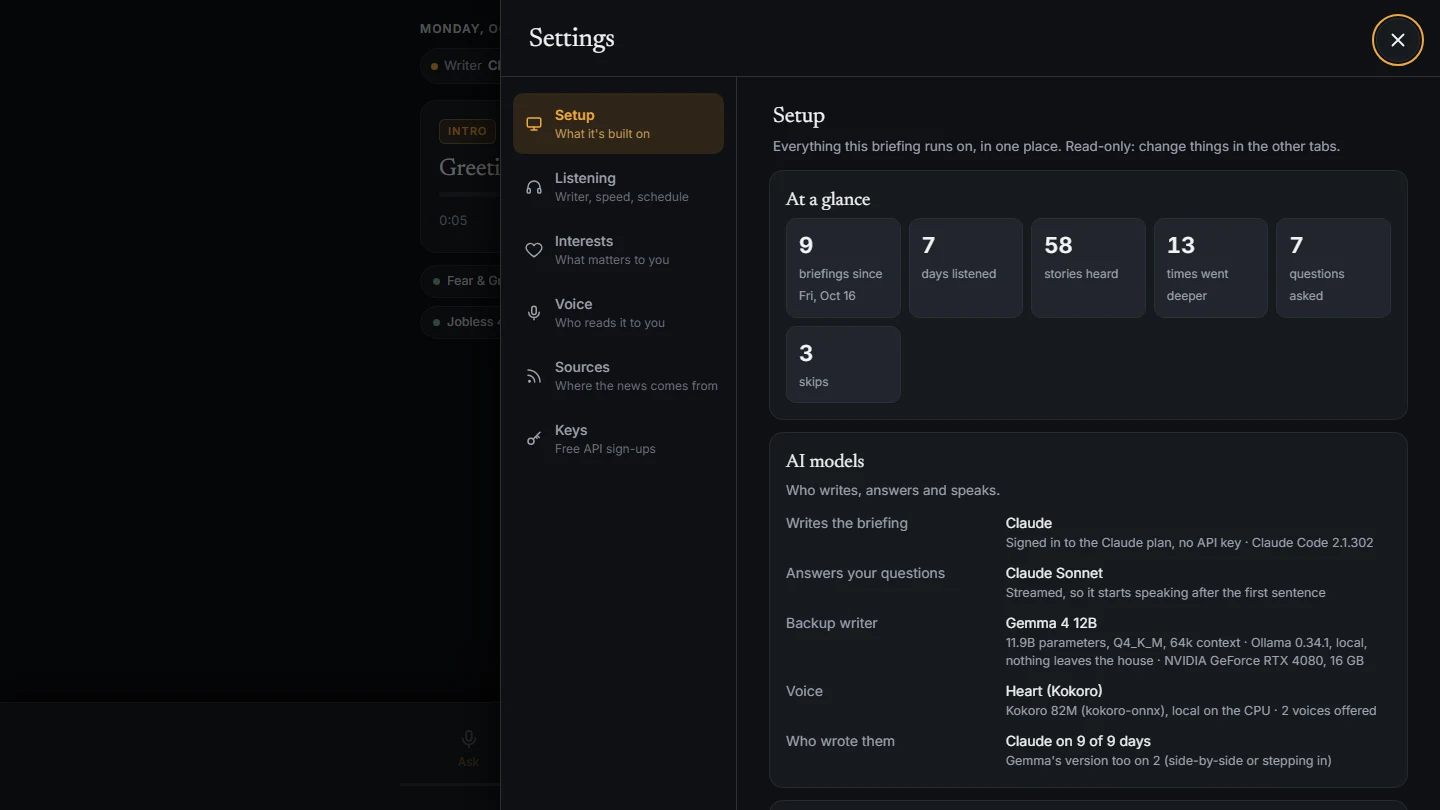
A briefing at 06:00 every weekday and Saturday since Oct 19, and I listen daily: 58 stories heard, 13 deeper dives and 7 spoken questions so far. Answers to a question start playing 3.4 to 6.2 seconds after I ask, down from about 10. A 533-check regression suite covers the page, the API and the writer.
phone → home server → workstation → Claude, Gemma, Kokoro
- Oct 26 Setup screen: every model, schedule and health check on one read-only page
- Oct 25 Answers streamed and recorded sentence by sentence: first audio in 3.4 to 6.2 s instead of about 10
- Oct 24 A freeze on the iPhone traced with a timeline logged from the phone for every question
- Oct 20 Ask about this: questions out loud, answered in the briefing's voice
- Oct 19 First scheduled briefing; interests, skip review and "already heard" filtering
- Oct 18 Listening from anywhere behind a sign-in; settings stay home-only
- Oct 17 Claude picked as the writer, Gemma as the automatic fallback, Kokoro as the voice
- Oct 16 Writer bake-off on the same pull: Claude about 90 s, Gemma 39 s, gpt-oss 191 s
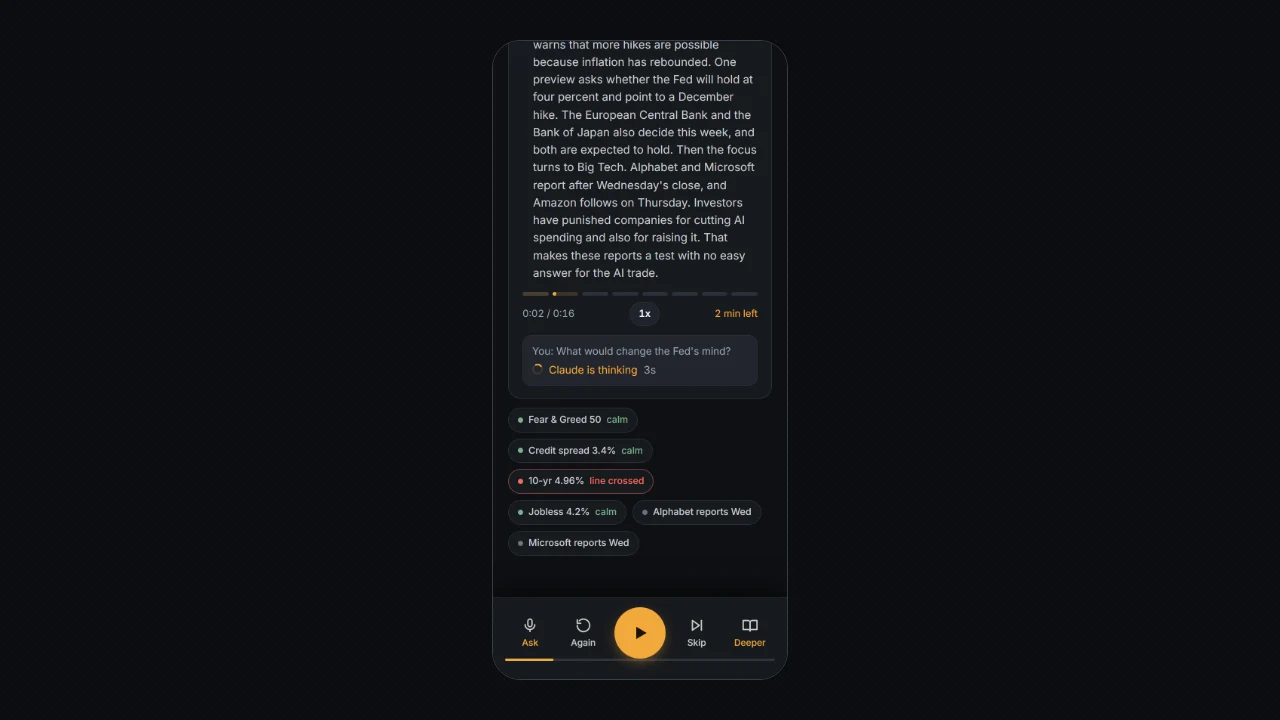
I'd test the voice features on the phone from the first day. The desktop test suite passed while asking a question froze on my iPhone, and the server and worker logs showed a finished answer every time. What found it was a timeline logged from the phone itself. I'd also stream the answer from the start: waiting for the whole answer before recording any of it cost several seconds on every question.